The Unreasonable Effectiveness of the Training-Free Multimodal Harness
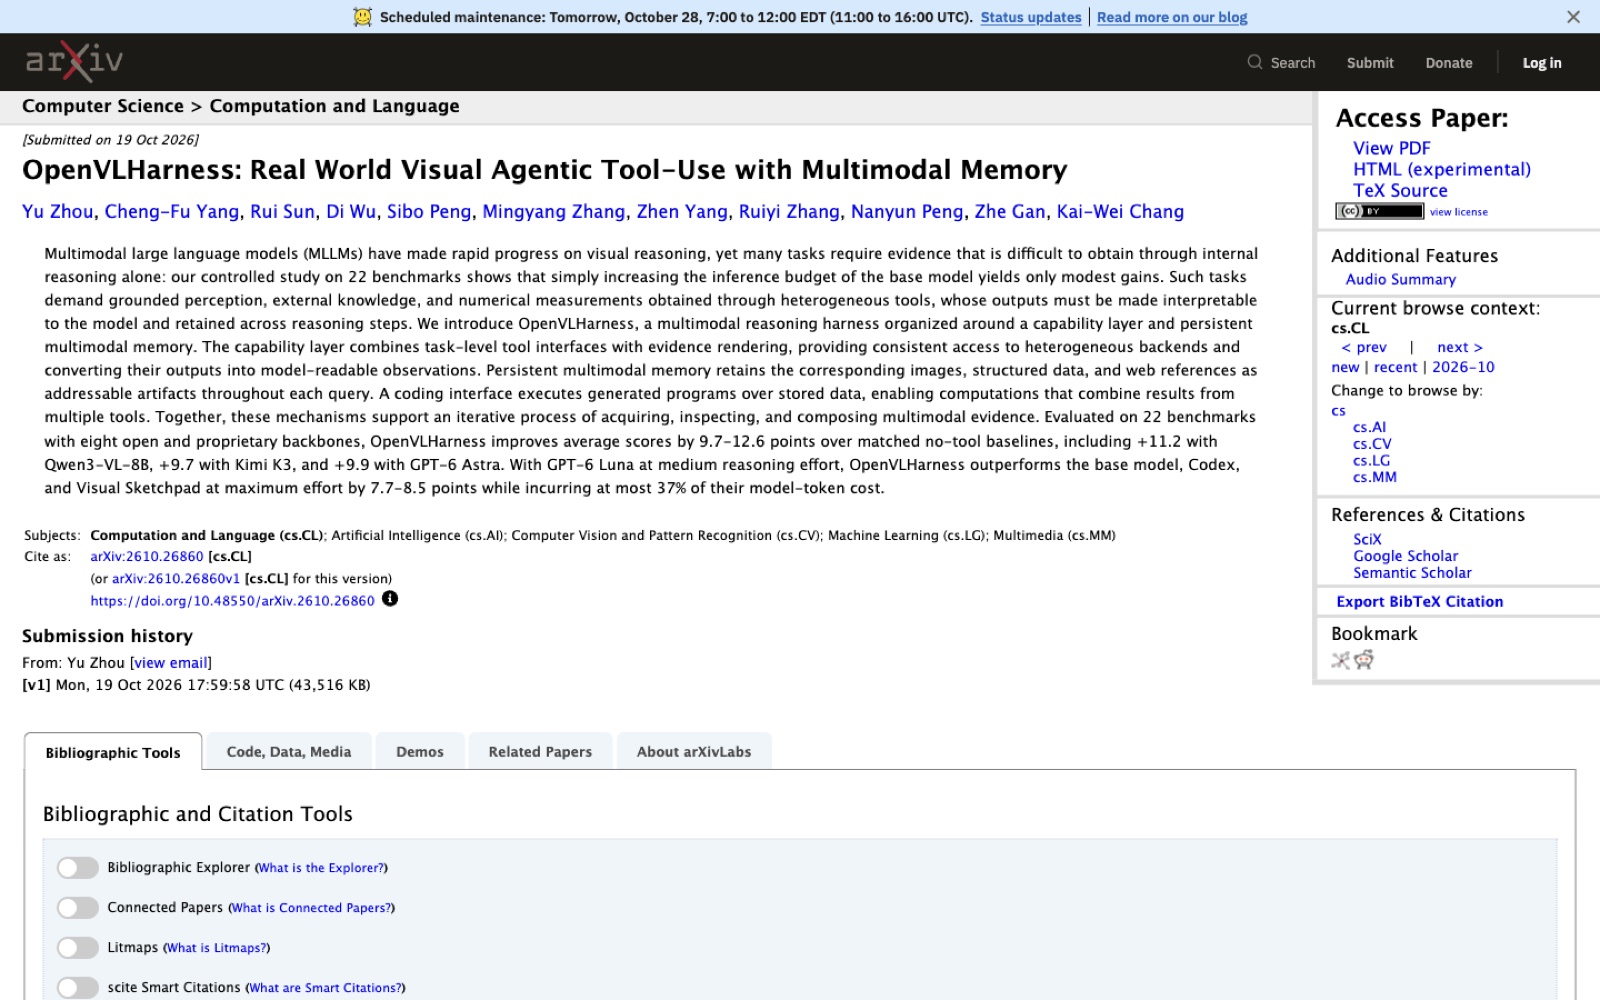
Frontier multimodal models do not need post-training parameter updates or brute-force internal test-time compute to solve intricate visual tasks; they need an external execution runtime that decouples persistent memory from the prompt context. As practitioners, we are routinely pushed toward a false dichotomy: either fine-tune an end-to-end vision-language checkpoint on custom agent trajectories, or let a frontier model chew through thousands of internal reasoning tokens hoping it hallucinates the correct spatial and factual relationships. I take a different view. The heavy cognitive lifting in multi-step visual reasoning is not happening within the model's static weight matrices, but within the harness that structures tool interaction, tracks intermediate state, and prevents context degeneration.
When we inspect how visual agents have evolved, the bottleneck has never been perceptual recognition alone. It has always been the mechanics of maintaining intermediate evidence across sequential operations without polluting the model's visual context.
timeline
    title Evolution of Visual Tool-Use Paradigms
    section Symbolic Execution
        Programmatic Pipelines : ViperGPT and VisProg generate one-shot Python code with frozen CV APIs
    section Context Accumulation
        Flat ReAct Loops : Interleaved text and raw base64 images appended directly to prompt history
    section Latent Search
        System Two Scaling : Unassisted test-time reasoning compute relying entirely on internal weights
    section State Decoupling
        OpenVLHarness : Out-of-band persistent multimodal memory isolating addressable artifacts from context tokens
In early approaches like ViperGPT or VisProg, visual problem-solving was formulated as zero-shot Python program generation. The model wrote a symbolic script that called dedicated computer vision primitives, but once execution started, the model lost the ability to reactively inspect unexpected visual evidence or correct runtime faults. The ecosystem responded by adopting iterative tool-calling loops. Yet appending full-resolution crops and raw tool outputs into a standard conversation window quickly exhausts the model's attention budget.
By contrast, the training-free harness pattern introduced in OpenVLHarness treats the base model as an orchestrator over a structured runtime. The base model performs visual inspection, executes dynamic Python code, and grounds findings via web retrieval without touching a single weight parameter. Crucially, the inference harness does the heavy cognitive lifting by structuring tool interaction rather than assuming larger model weights will magically resolve state accumulation. This approach echoes themes I explored in Should You Switch Your Agent Harness to Anvaya? Only if Orchestrator Memory Is Your Bottleneck, where controlling memory topology outside the context window yields higher reliability than scaling prompt depth.
Why External Scaffolding Looks Like a Step Backward
The machine learning consensus instinctively resists external agent harnesses, viewing runtime wrappers as an engineering compromise that will inevitably be superseded by end-to-end learning. The prevailing thesis argues that wrapping vision models in Python execution loops, web scrapers, and external state stores is merely brittle scaffolding. The assumption is that next-generation foundation models—armed with native function calling and scaled test-time compute—will internalize these agentic patterns directly into their latent search passes.
That assumption collapses when confronted with the physical reality of visual grounding.
In purely textual reasoning, scaling test-time compute means unrolling sequential tokens inside a linear key-value cache. In multimodal environments, however, recursive self-reflection inside the context window is mathematically and financially unsustainable. Every time an agent crops a sub-region of an image to inspect fine-grained detail, runs an OCR pass, or extracts tabular data, feeding those raw visual patches back into the prompt inflates the vision token footprint by hundreds or thousands of tokens per step. If an agent requires six iterative steps to verify serial numbers across multiple components, accumulating intermediate high-resolution crops causes catastrophic context bloat. The attention mechanism suffers from needle-in-a-haystack degradation, and Time to First Token escalates exponentially on every subsequent turn.
Furthermore, internal reasoning weights cannot substitute for deterministic computation or live open-world knowledge. A model cannot reliably approximate complex coordinate geometry or statistical transformations through next-token prediction when a five-line Python script executing in a standard environment does so with zero error. Attempting to force an unassisted model to internally compute what an external Python interpreter can resolve deterministically is an inefficient allocation of test-time compute. The resistance against external scaffolding mistakes architectural modularity for technical debt; externalizing state storage and programmatic execution is the only sustainable path to prevent visual token collapse during multi-step reasoning.
Inside OpenVLHarness: Decoupling Artifact Storage from Context Tokens
The technical architecture introduced by Zhou et al. (arXiv:2610.26860) formalizes this modular division of labor through a tripartite framework: a Capability Layer, a Persistent Multimodal Memory, and a Dynamic Coding Interface. Instead of dumping raw sensory data and external query dumps directly into the conversation history, OpenVLHarness cleanly separates what the model reads from what the model manipulates.
mindmap
  root(OpenVLHarness Architecture)
    Capability Layer
      Tool interface abstraction
      Evidence rendering pipeline
      Observation standardization
    Persistent Multimodal Memory
      Immutable artifact storage
      Image crop handles
      Tabular dataframe cache
      Web search payload store
    Dynamic Python Interface
      Deterministic script execution
      Programmatic artifact manipulation
      Runtime environment isolation
The Capability Layer serves as the translation bridge. When tools execute across heterogeneous domains—perceptual zoom tools, headless web search, or an interactive Python shell—their outputs vary wildly in format. The Capability Layer intercepts these disparate returns and subjects them to an evidence rendering pass. Rather than stuffing multi-megabyte payloads or massive pixel grids into the prompt, the system registers raw media into the Persistent Multimodal Memory as an addressable artifact with a distinct handle, while rendering a compact, standardized observation for the model's immediate reasoning turn.
Once stored in this persistent memory, artifacts do not vanish into an ephemeral Python process, nor do they dilute the global prompt. The Dynamic Coding Interface allows the model to emit Python snippets that directly reference these stored handles. If an agent needs to calculate pixel intensity distributions across an intermediate crop or run pandas aggregations over an extracted table, it writes code targeting the artifact handle directly. The execution happens inside a sandboxed environment, returning only the targeted answer to the context.
This separation yields striking empirical advantages across both open-weight and frontier proprietary models. In the research by Zhou et al., OpenVLHarness delivers benchmark improvements between +9.7 and +12.6 points across varied models, including Qwen3-VL-8B, Kimi K3, and GPT-6 Astra/Luna. Because the context window is spared the burden of storing raw intermediate images across iterative rounds, the harness caps test-time token expenditure at 37 percent or less compared to baseline models relying on brute-force internal chain-of-thought scaling. As with runtime bounding mechanisms discussed in How agentloop Enforces Run Bounds on LLM Agents Without a State Graph, structuring the execution substrate turns an unruly reasoning loop into a disciplined, cost-bounded evaluation pipeline.
The Virtual Memory Analogy: Why State Belongs in Runtime Storage
The architectural leap required for robust visual agents is not larger context windows, but a strict separation between working registers and external storage. When operating systems faced the physical limits of hardware RAM decades ago, computer architects did not solve the problem by demanding infinitely wider address buses. They built virtual memory paging and file descriptor tables. The CPU registers remained tiny, dedicated strictly to active computation, while the operating system managed pointers to heaps, caches, and disk blocks out of band.
Today's multimodal agent stacks are repeating the exact architectural mistake early computing made before memory management units existed. Engineers treat the vision-language context window as an undifferentiated heap, stuffing raw sensory payloads, full-resolution image arrays, and verbose execution dumps into the prompt history. The prompt was never meant to be a database; it is an active register file.
flowchart TD
    subgraph VLM["Vision-Language Context (CPU Registers)"]
        A["Active Instructions & Goals"]
        B["Compact Reasoning Traces"]
        C["Handle Table (Pointers: #crop_01, #df_tax)"]
    end

    subgraph Runtime["Runtime Memory (Paged Heap / Disk)"]
        D["High-Res Image Crops (Pixels)"]
        E["Structured Dataframes (Tabular State)"]
        F["Retrieved Web Payloads (HTML / Text)"]
    end

    C -.->|"Dereference on demand via code"| D
    C -.->|"Query via pandas"| E
    C -.->|"Scrape via parser"| F
When an agent operates through addressable handles—such as referencing a cropped inspection region as an immutable pointer rather than a massive array of base64 vision tokens—the context window retains only the metadata necessary to orchestrate the next operation. The underlying pixel matrices, parsed dataframes, and scraped web trees live in runtime memory managed by the harness. If the model needs to inspect or transform an asset, it delegates the operation to the dynamic Python runtime using the handle, exactly as a process requests I/O using a file descriptor.
I anticipate that future production agent architectures will converge entirely on handle-based execution runtimes rather than expanding monolithic context allocations. Shoving tens of thousands of vision tokens into the key-value cache across iterative loops degrades self-attention and spikes operating costs. By enforcing an operating-system-grade boundary between active prompt registers and external artifact stores, the harness keeps the model's attentional focus razor-sharp while providing an unbounded storage backing for intermediate evidence.
The Production Runtime Blueprint: Sandboxes, Pointer Registries, and Empirical Verification
Building a dependable visual agent in production requires translating these conceptual layers into hardened infrastructure. The most critical operational reality to confront is that executing dynamically generated Python code over multimodal inputs exposes an immediate remote code execution vector. An agent reading arbitrary documents, schematics, or user-submitted screenshots will inevitably encounter text that attempts prompt injection. If an image contains adversarial text instructing the model to dump environment variables, wipe directories, or phone home to an external server, an unconstrained code interpreter will dutifully execute those commands.
To mitigate this threat, the execution runtime must enforce ephemeral isolation at the micro-VM layer using technologies like Firecracker or gVisor. Each execution pass should spin up in a disposable, network-isolated container with read-only root filesystems, tight memory ceilings, and rigid CPU quotas. Tool artifacts must be exposed strictly through an immutable, read-only volume mount. When the Python interface processes an image handle, it writes its derived output to an ephemeral scratchpad that the Capability Layer validates, serializes, and assigns a new immutable handle before exposing it back to the orchestrator.
Beyond security isolation, production teams must build a concrete pointer registry. Rather than allowing the model to invent arbitrary file paths or variable names, the Capability Layer should maintain an explicit schema where artifacts are assigned deterministic, typed references. When an OCR tool identifies a visual sub-region, the harness registers the bounding box and generates an addressable reference that exposes specific programmatic methods to the dynamic Python interface.
For teams evaluating whether to adopt a handle-based memory harness over a standard flat ReAct loop, I recommend establishing an empirical outside check before refactoring production code: construct an automated five-turn synthetic benchmark simulating an iterative document inspection task. In the baseline control run, feed the model an initial high-resolution image and append intermediate crops directly into the conversational message history on each turn, recording total vision tokens consumed, cumulative API billing, and Time to First Token across each step. In the parallel experimental run, configure the harness to store crops on an external scratch disk, injecting only a lightweight text reference and a downsampled thumbnail into the prompt, while allowing a sandboxed Python step to compute pixel statistics on the full-resolution crop on demand.
Running this comparison across fifty representative document inspection queries will instantly expose the divergence: while the flat context approach experiences quadratic cost increases and attention degradation by turn four, the handle-based artifact pattern maintains flat per-step token overhead and consistent inference latencies throughout the entire multi-turn trajectory.
Where the Scaffolding Fractures: Reference Drift, Resolution Traps, and the Honest Hedge
Despite the impressive benchmark improvements demonstrated by OpenVLHarness, relying on external scaffolding without parameter fine-tuning is not an architectural panacea. When we eliminate model fine-tuning and rely strictly on runtime prompting, we shift the entire burden of protocol compliance onto the base model's general in-context reasoning capabilities. In production, this trade-off exposes distinct failure modes that pure benchmark leaderboards tend to obscure.
The most prevalent runtime breakdown is artifact reference drift. Because the Python runtime executes code ephemerally between reasoning passes, models frequently hallucinate variable names or handles from earlier turns that were never persisted into the global artifact registry. The agent attempts to query an unassigned handle or assumes a variable instantiated in turn two is still resident in Python memory during turn four, triggering runtime exceptions that derail the execution chain.
A more insidious mechanical trap is coordinate frame distortion. When the capability layer extracts a visual sub-region to allow detailed inspection, the cropped image establishes a localized coordinate system. If the model subsequently detects an anomaly inside that crop and attempts to emit a bounding box or spatial transformation back to the parent image, it frequently conflates the crop's local pixel coordinates with the global frame.
Furthermore, training-free harnesses struggle when multi-tool modalities produce conflicting evidence. Visual perception is probabilistic and approximate, whereas code execution is deterministic and web retrieval is noisy and external. When a web search query retrieves documentation that directly contradicts what the vision model observes in a diagram, an untuned model lacks the calibration to resolve the tension. The system frequently enters circular verification loops, re-running queries without converging on a decision until hit by an external timeout.
We must also be clear about what the current research does not show. The published findings demonstrate strong gains on top-tier frontier backbones like GPT-6 Astra/Luna, Kimi K3, and Qwen3-VL-8B, but they do not prove that this harness functions reliably on smaller, instruction-poor open weights that lack frontier instruction-following discipline. Nor does the research provide production recovery protocols when multi-turn tool loops exceed latency budgets. Wrapping multimodal models in external memory and code interfaces is a powerful bridge toward reliable visual autonomy, but treating it as a total replacement for domain-specific agent alignment mistakes runtime engineering for solved intelligence.
Resources
Updated 2026-10-19 by Mehran Mozaffari.
Related posts
1 November 2026
Code Mode vs Function Calling for Multi-Step Agents
1 November 2026
Offline Trajectory Scoring Replaces the Prompt Engineering Treadmill
1 November 2026
Should You Build Your Enterprise Agent Semantic Layer on NVIDIA Auto Ontology? Not Yet
31 October 2026
Unreal Engine Skills for Claude Code: How Epic Bypassed the Binary Asset Barrier to Mutate Live Viewports
30 October 2026
Agent Memory Was an Indexing Problem All Along
29 October 2026
How 3D OS Turns a Coding Agent into a Six-Department Animation Studio Without a GUI